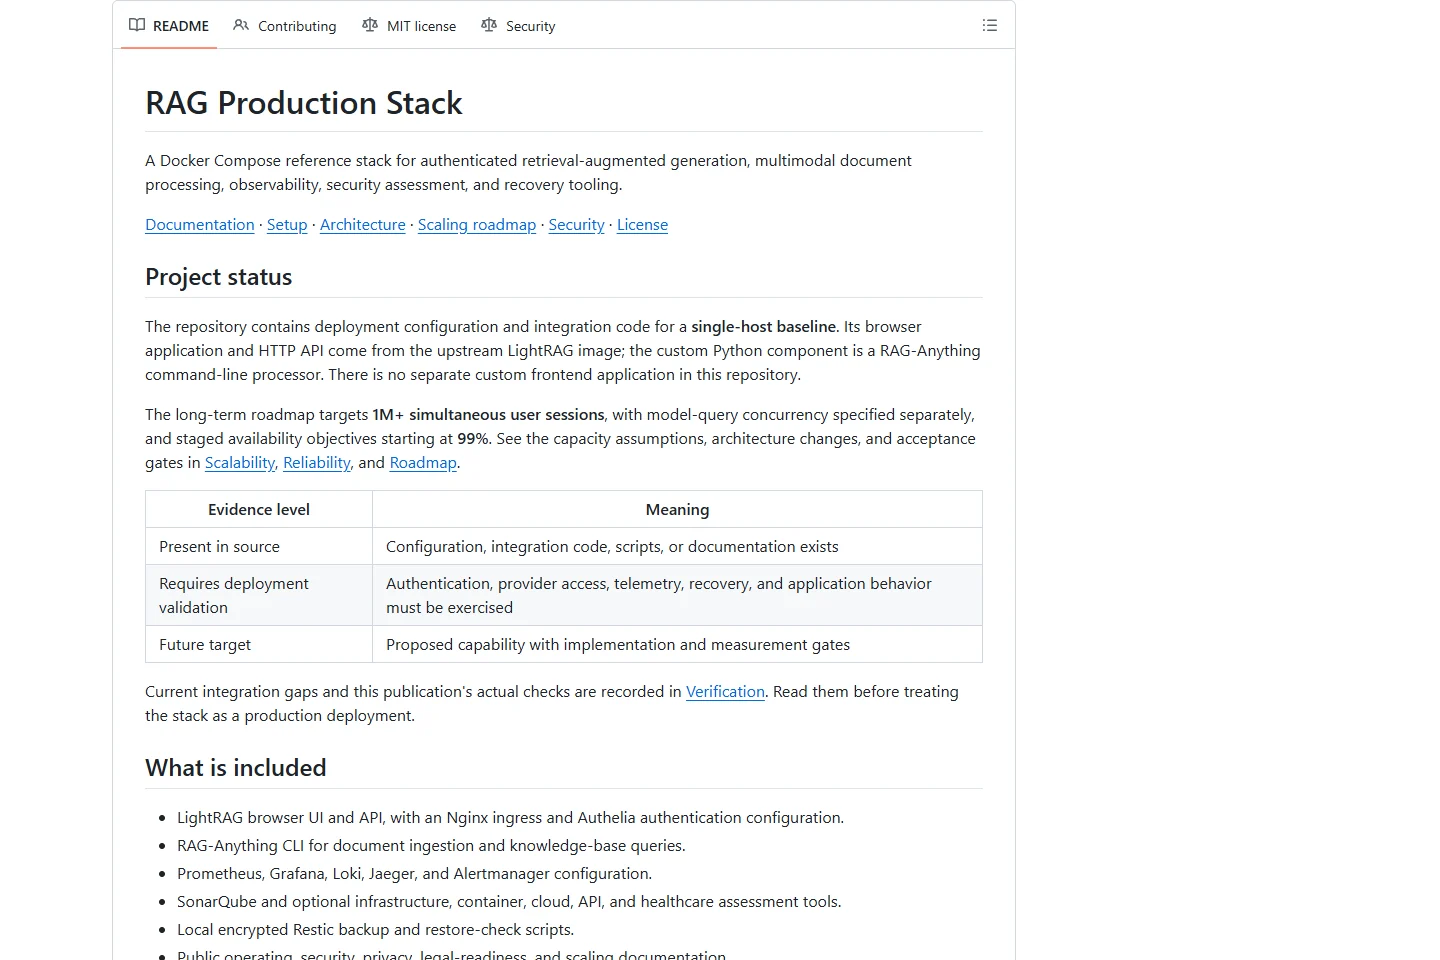
RAG Production Stack
Open-source retrieval stack: nine core services, authentication, network isolation, metrics, logs, traces and encrypted backups.
Source-reconciled infrastructure
Independent build
My own retrieval infrastructure repository. Documents configuration and source intent, not a live deployment.
THE ENGINEERING
Containerized retrieval infrastructure with nine core services and fourteen profile-activated services, authentication, network isolation, metrics/logs/traces and encrypted-backup workflows. Published as MIT-licensed open source, with hosted Gitleaks, Semgrep and Bandit checks passing. The documentation establishes configuration and source intent; it does not claim a currently healthy deployment or compliance certification.
BEFORE → AFTER
Real problems from this build, what I changed and the verified result.
- CASE 01Before
Most RAG setups stop at 'it works on localhost', with no auth, observability or scanning story.
After9 core services with source-defined health checks, plus 14 profile-activated services.
How I fixed itWrapped the engine with authenticated access, network isolation, metrics/logs/traces and profile-activated scanning.
- CASE 02Before
The repository needed to be safe to publish.
AfterHistorical, staged and public-tree secret scans found no matches before publication.
How I fixed itRemoved secrets, machine-specific paths and cloud identifiers, replaced them with environment variables, and excluded scanner output from version control.
- CASE 03Before
The documentation claimed more than the stack actually did.
AfterDocs that match the source, which matters most for a security-focused project.
How I fixed itReconciled the docs against the actual service definitions and split core from on-demand services.
Evidence reviewed: Open-source public edition, September 24, 2026