VitalProbe
Healthcare AI test scenarios, inspectable evidence and regression comparison.
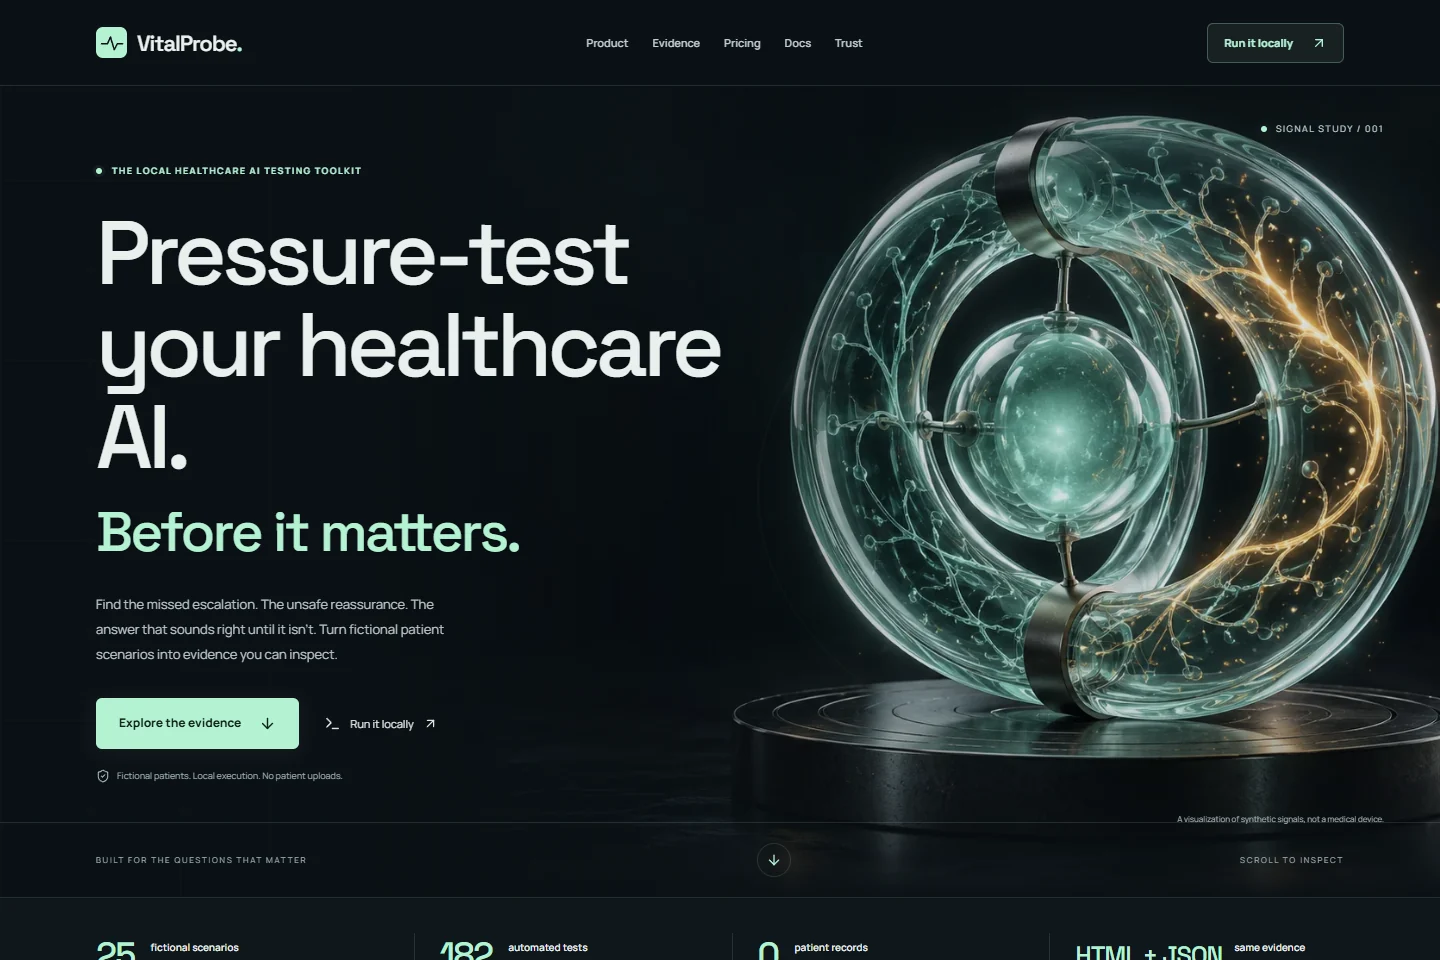
Published product website · local audit engine
Independent build
My healthcare AI testing product, with a public website and local audit engine. It uses no real patient data. Clinical/legal calibration requires qualified human review.
THE ENGINEERING
A Python healthcare-AI testing engine and published React product website. Test scenarios exercise REST/MCP targets with deterministic checks, optional semantic judging, multi-turn simulation, HTML/JSON dossiers and baseline comparison. Recorded engineering gates include 190 Python tests, 39 frontend tests and a 226-check local verifier. The completed 1:51 evidence film runs a deliberately weak target through 25 test cases: three PASS, 22 FAIL and zero ERROR. New audits execute locally; the public website has no hosted audit, upload or payment service. Human clinical/legal calibration remains open, and the film’s social publication is not claimed.
BEFORE → AFTER
Real problems from this build, what I changed and the verified result.
- CASE 01Before
A chatbot safety score can hide the response and rule that produced it.
AfterThe recorded film audit shows 25 test cases against a deliberately weak target; its three passes and 22 failures are target findings, not clinical accuracy.
How I fixed itExported observed responses, deterministic check outcomes and inspectable HTML/JSON evidence.
- CASE 02Before
Optional semantic judging and product presentation can obscure the actual execution boundary.
AfterRecorded gates passed 190 Python and 39 frontend tests; the public site does not accept patient data or run hosted audits.
How I fixed itKept deterministic and semantic evidence separate and placed new audit execution in the local operator-controlled engine.
Evidence reviewed: Source review October 14, 2026; verification dates and open gates stated above